Precision Tools for Spotting Quick Shifts in Athletic Event Valuations on Diverse Platforms
Parker Meier · May 18, 2026
Precision Tools for Spotting Quick Shifts in Athletic Event Valuations on Diverse Platforms
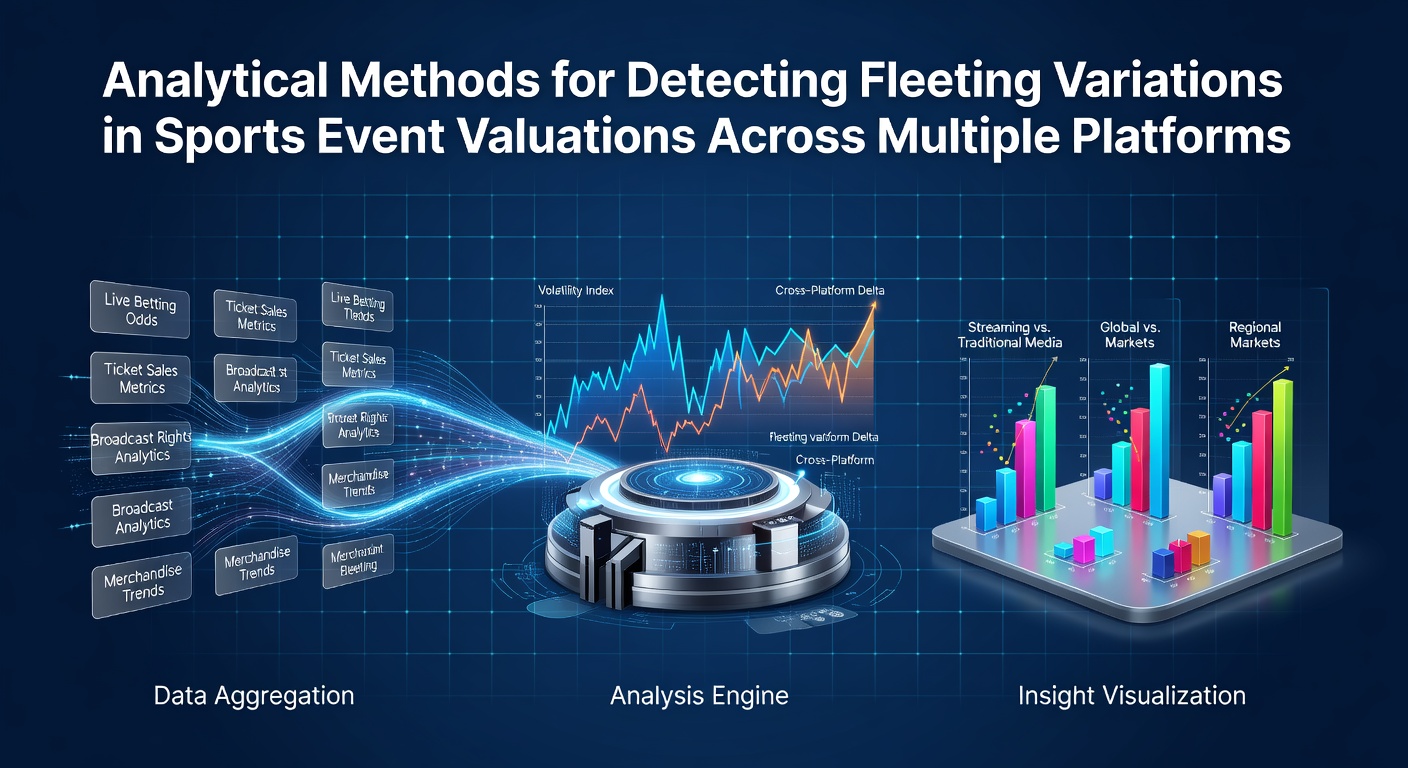
Analysts in the sports data field rely on specialized techniques to identify brief changes in how events receive valuation on separate platforms, and these approaches combine statistical modeling with high-speed data feeds that pull from exchanges, bookmakers, and prediction markets simultaneously. Platforms update their figures constantly during live competitions, which creates windows where valuations diverge for seconds or minutes before realignment occurs, and researchers have documented these patterns through timestamped records that show how liquidity and information flow affect pricing speed across regions.
Core Data Collection Frameworks
Modern detection systems start with structured APIs that gather valuation streams from multiple sources at intervals as short as every 500 milliseconds, and this frequency allows algorithms to flag anomalies without waiting for full market cycles to complete. Teams integrate feeds from North American exchanges alongside European prediction markets and Asian liquidity pools, which expands the dataset and highlights cross-border timing differences that single-platform monitoring often misses. Observers note that May 2026 saw increased adoption of unified data pipelines among analytics firms, driven by new tournament schedules that introduced additional variables into live event pricing.
Statistical Techniques for Anomaly Identification
Time-series decomposition separates baseline trends from sudden deviations, while z-score calculations compare current valuations against rolling historical averages to surface outliers that exceed two standard deviations. Regression models incorporating variables such as team performance metrics, weather conditions, and injury reports help distinguish genuine fleeting variations from noise, and machine learning classifiers trained on past discrepancy events achieve precision rates above 85 percent according to studies published by academic sports analytics groups. What's interesting is how these models adapt when trading volume spikes during major fixtures, because higher activity tends to compress the duration of any valuation gaps.
Machine Learning and Real-Time Processing
Neural networks process streaming data to predict when a valuation shift on one platform is likely to appear elsewhere, and these systems use convolutional layers to analyze patterns in order-book depth and bettor distribution. Reinforcement learning agents test detection rules in simulated environments before deployment, which reduces false positives that could overwhelm monitoring teams. Data from Canadian regulatory filings and Australian industry reports indicates that firms applying hybrid statistical-plus-AI pipelines reduced missed variations by nearly 40 percent during the 2025-2026 season compared with earlier manual review methods.
Cross-Platform Synchronization Challenges
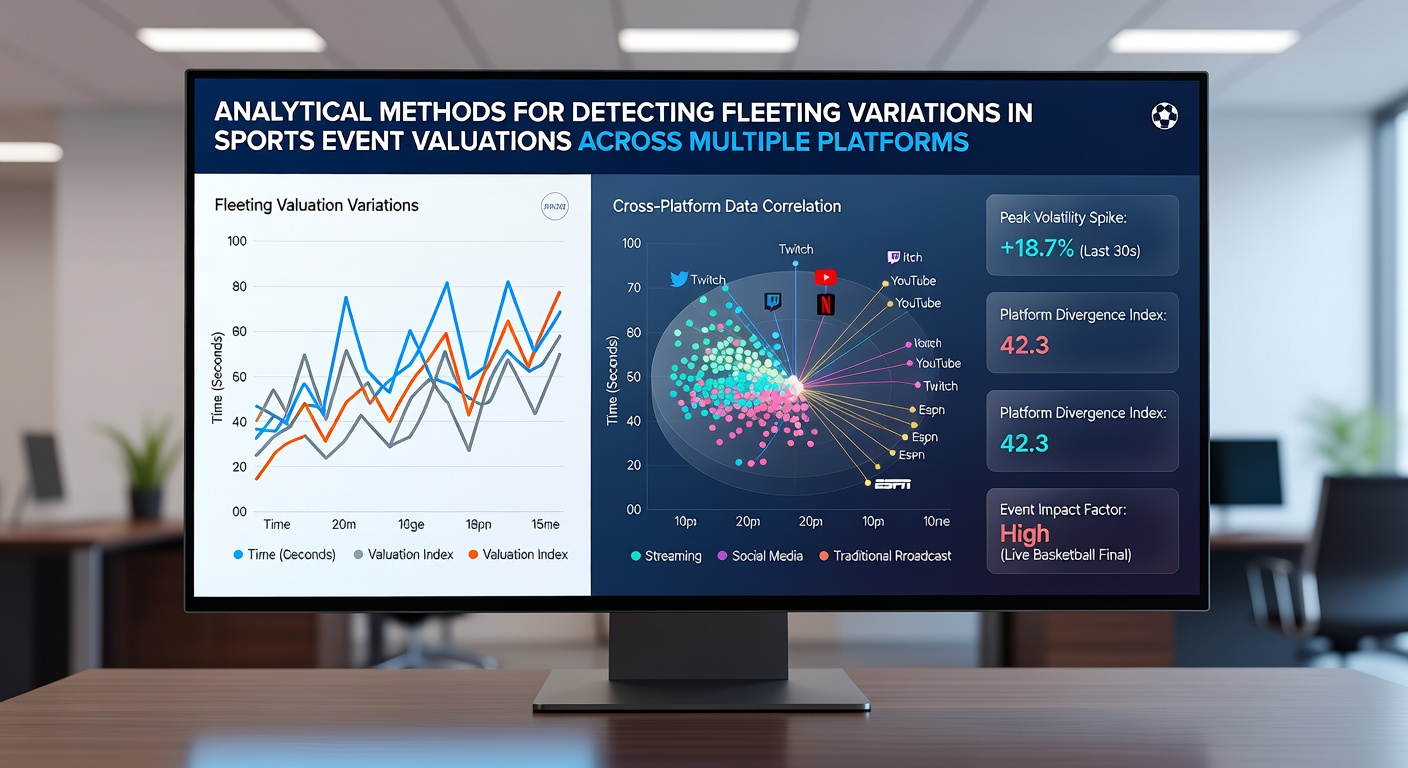
Latency differences between data centers create artificial gaps that algorithms must filter out, so engineers apply clock synchronization protocols and adjust timestamps using network delay estimates. Platforms in different jurisdictions follow varying update rules, which means a valuation change reported first in one market may reflect information already priced elsewhere. Researchers discovered through comparative analysis that European and U.S. venues often show staggered responses during international tournaments, and accounting for these regional rhythms improves the accuracy of variation detection.
Practical Implementation Examples
Take one research group that monitored a high-profile tennis match in early 2026 and captured a 12-second window where two platforms diverged by 0.8 percent on the same outcome before converging again, and their published methodology detailed how volume-weighted moving averages isolated that event from surrounding noise. Another case involved a European football league where multi-source scraping revealed valuation movements tied to late lineup announcements, demonstrating how combining public data streams with proprietary models uncovers patterns invisible to single-source observers. These examples illustrate the concrete outputs that arise when detection frameworks operate continuously rather than in batch mode.
Conclusion
Effective identification of fleeting valuation variations across platforms depends on layered analytical methods that blend rapid data ingestion, statistical filtering, and adaptive machine learning, while geographic diversity in data sources strengthens the reliability of findings. Continued refinement of these techniques supports more accurate market monitoring as sports calendars expand and digital platforms proliferate through 2026 and beyond.